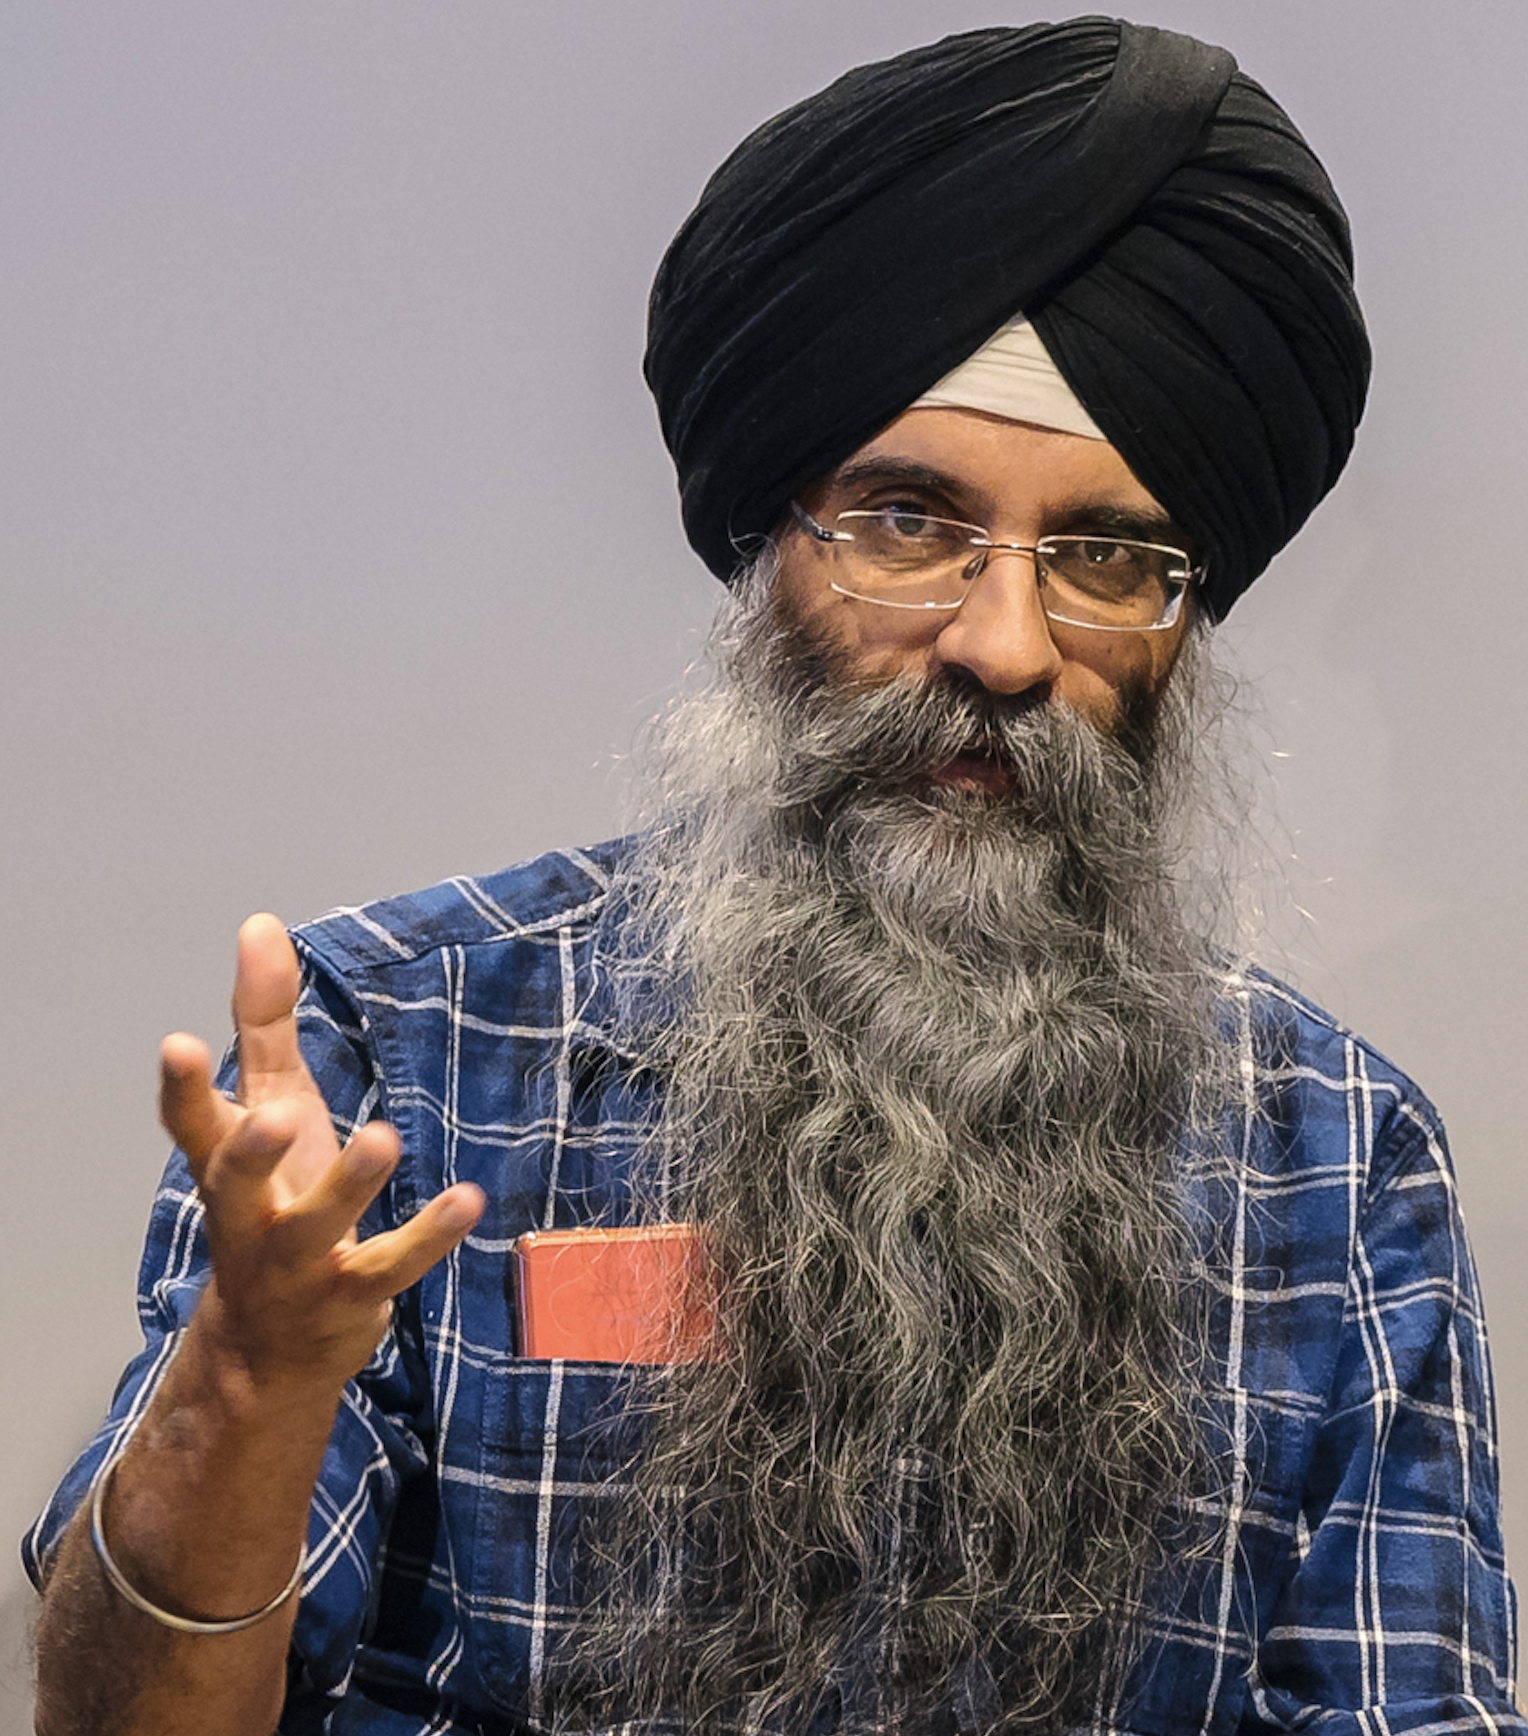
Dr Raminderpal Singh
AI Engineer (Life Sciences)
Global Head of AI/GenAI Practice · 20/15 Visioneers
Founder · HitchhikersAI
I'm an AI Engineer and entrepreneur enabling Scientific R&D organisations to move from AI‑curious to AI‑led — starting with life sciences, where I've spent the last 20 years building depth in the industry's priorities, risks, and resistance to change. I work through practical software, open‑source in‑silico workflows, and the organisational change needed to make it stick.
 Compound Insights
Drug compound intelligence dossiers — public data and literature-grounded inference
First deployment of fred — Pilot dossier on imatinib (CHEMBL941). Runs on the fred reasoning core (v0.2.0) against the compound2 data package.
Rigorously-cited output — Targets, pharmacokinetics, and regulatory history. Every claim links back to a public-data or literature citation.
 fred
Continuous knowledge-graph inference for pre-clinical drug discovery
Reasoning core, embedded as a module — A private, secure, ground-up ReAct module that runs async in a host agentic framework. Continuously infers hidden edges and nodes in the host’s knowledge graph as new literature and data arrive.
LLM-agnostic, isolated deployment — Reasoning models (cloud and local) wrapped per their tokenizer, context, and tool-calling behavior. Packaged into secure isolated containers per scientific R&D project, each its own tenant with its own private graph.
↗ projectfred.dev publishes head-to-head reasoning comparisons against Opus 4.7; fred is under active development — read the architecture →
 ScienceClaw
Autonomous research platform for life sciences
Market Research — Email a question, get a verified memo back. Grounded in accumulated evidence, cross‑model verified, with gaps flagged.
Trial Intelligence — Detects oncology trials whose design deviates from empirical baselines. Investigates anomalies through six public APIs. No anomalies, no email.
Decision Support Without Agentic Engineering
Positioning paper, preprint — one pinned reasoning engine and a human who decides
Right about process, wrong about architecture — I keep agentic engineering’s external checks and human judgment, and reject many agents converging on an answer where a scientist or a committee must decide.
Two example applications — How Compound Insights and the SIM Framework are built and structured, and why the conventional coding-agent build was not taken.
September 2026 — ↓ download the PDF
SLAS Discovery
Guest Editor — Special Issue: Real‑Life Case Studies in AI‑Driven Drug Discovery Workflows
AI is everywhere there is data — data science, bioinformatics, cheminformatics, ML, LLMs. One community, many labels.
Deploying it is now routine — academics, vendors and labs have made AI mainstream.
Share what happened, failures included — so others can learn.
The stories get heard — an active readership of practitioners and academics.
Co-edited with Srijit Seal, PhD. Submissions until December 15, 2026 — ↗ read the call for papers
AI Drug Dev
AI‑assisted software development for life sciences
Rapid Prototyping — The scientist describes the workflow; AI implements a working prototype in hours, not quarters.
Constrained Hardening — AI converts the prototype to production‑grade code under hash‑verified enforcement and a 30‑check assessment.
project fred
Continuous knowledge-graph inference for pre-clinical drug discovery. fred is a private, secure, ground-up ReAct agentic module focused on scientific applications. It runs async in the background, continuously inferring hidden edges and nodes in a knowledge graph from updated literature and experimental data — refining the host framework’s view of the domain as new information arrives. It is not a turn-by-turn agent that produces one memo and stops; it is a long-running reasoning core designed to be embedded in a host agentic framework that owns the operator-facing surface and the task orchestration. The first deployment of fred’s reasoning core is the Compound Insights Inference Engine — a pilot drug-compound dossier on imatinib (CHEMBL941), running on fred v0.2.0.
 ← see fred on Active Projects
How fred actually runs
Four properties that distinguish fred from “a ReAct agent that calls PubMed.”
Validating the reasoning core
The continuous graph cannot be trusted if the unit reasoning task is not accurate. The current evaluation runs fred’s reasoning core against Claude Opus 4.7 on the same biomedical research questions, head-to-head. fred runs each question three times with citations independently judged; Opus runs each once with web search. A separate Opus chat then reads both sides and produces a qualitative comparison. The point is not that fred “beats Opus” — it is whether fred’s specialized reasoning core produces output that holds up against a frontier general-purpose model when citations can be mechanically checked. Full run logs and comparisons are published openly on projectfred.dev.
Scope disclaimer: the continuous knowledge graph is the target architecture, not what is currently shown publicly. The published evidence validates fred’s reasoning core doing one unit task at a time. The ingest / infer / emit loop that turns those unit outputs into a continuously refined private graph is in active development.
Where agentic engineering fits life sciences R&D, and where it does not
Agentic engineering is the current direction of the software market: coding agents that read the repository and run the commands, hooks that block a rule violation before it lands, and products built as teams of specialist agents that plan, research, write and review one another. For most software that direction is correct. Where the work decomposes into independent pieces and a wrong answer is cheap to check, as in ScienceClaw’s autonomous research pipelines, many agents are the right design.
I also build a different kind of system: decision support for pre-clinical drug discovery, where a human committee makes a contested scientific decision and the software assembles cited evidence for it. Compound Insights and the SIM Framework are that kind of system. On that work I have adopted part of the trend and declined part, and the division follows one question: can every output be traced to its evidence, attributed to the engine version that produced it, and reproduced?
Once the tooling language is removed, agentic engineering is a claim about process. An LLM cannot verify its own output, so quality comes from external verification at gates, a human holding the judgment at those gates, and failures converted into standing controls. I arrived at that process independently and apply it without exception. Every science and governance decision is mine, recorded before it takes effect. Every write passes its gates before I say go. Every prediction is scored, and every miss stays on record with the measurement that produced it. The difference between my method and a coding agent is a single row of the table below: who executes the deterministic layer. The agent runs the commands. I run them.
My environment is one browser tab and one terminal: the Claude.ai app writes the code, I download the file, run the command and paste the result back, and control lives in standing settings and project instructions rather than in the chat. The environment, the three principles behind the gates, the failure patterns I have recorded and the check that catches each one are written up in full on ↗ AI Coding: a practical approach for scientists, with Compound Insights as the worked case study.
That substitution has a cost, and I state it plainly. A coding agent reads the live repository; I work from what I upload, so the model can edit a copy of a file when the live one has moved, and that is my most frequent error class. An agent executes faster than my turn rate, so it exposes new failure classes sooner, and its rules live in hooks that another person could run. Those costs are real. They govern how fast the method finds its own defects and whether it transfers to a second engineer. They do not govern whether the delivered software is correct or whether its outputs can be defended, and on those two the method is equal to current practice or ahead of it.
How I build
| What matters | My method: interactive sessions, I execute | Agentic engineering: coding agent with repository access and hooks | Advantage |
|---|---|---|---|
| Who decides the science and its governance | I do, one ruling at a time, recorded before it takes effect | The engineer, at gates; the agent proposes. With agent teams the judgment spreads across role prompts | Equal with a single agent; my method against many |
| Verifying that a change is correct | Every write gated by checksums, anchors, self-tests and a scratch render, then I say go | The same checks as hooks that block the action. Many-agent systems often satisfy them vacuously | Equal with a single agent; my method against many |
| Whether the model reads the live code | No. It reads what I upload, which is the source of my most frequent error class; the BAGIM write-up records four instances in one session, all caught by the change-script guards before any write | Yes, from disk | Agentic tooling |
| Who runs commands and reads results | I type, run and paste every block | The agent runs; the engineer approves | Agentic tooling on time; my method on comprehension |
| Record of what was believed against what was measured | Every prediction scored; every miss and every falsified idea kept, with the measurement that falsified it | Discarded by default when context is compacted | My method |
| Silent failures during the build | Rare in a session; they appear at session boundaries and are caught by continuation records | Rare if every hook fails loudly; common if not | Equal; set by discipline, not tooling |
| Throughput | Bounded by my turn rate; findings outrun triage | Higher on execution; evaluation campaigns stay serial because the reasoning engine runs one job at a time | Agentic tooling |
| My understanding of my own system | High; I read every line and every result | Erodes unless transcripts, and not summaries, are read | My method |
| A second person running the method | Not possible today | Possible where the rules are hooks and not prose | Agentic tooling |
What is inside the product
Inside the product the decision is different in kind. The market pattern is an orchestrator with planner, researcher, critic and writer agents passing state between them. Compound Insights and the SIM Framework use one reasoning engine, project fred, pinned to a version and never edited by the application that calls it. Every value carries the prompt version, the run id, the tool calls and the citation state that produced it. Non-determinism lives in one place, where campaigns of repeated runs measure it. The SIM Framework runs that single engine in three fixed roles, constructive, skeptical and arbiter, across repeated runs per claim, and publishes the spread of verdicts across runs instead of resolving it. Neither product emits a go or no-go. A human committee decides.
The published evidence supports the smaller design. The MAST failure taxonomy (Cemri, Pan, Yang et al., NeurIPS 2025) found that multi-agent systems’ gains over single-agent frameworks are often minimal, and located their failures in three places: specification issues, misalignment between agents, and weak verification. A hallucination in one agent becomes a fact for the next. What many-agent designs do well is fan out over independent subtasks. That is speed these products cannot use, because the engine serializes runs by design, and it would be bought with the two properties they exist to provide, attribution and reproducibility.
| What matters | My architecture: one pinned reasoning engine (project fred) | Many-agent architecture: orchestrator plus planner, researcher, critic and writer agents | Advantage |
|---|---|---|---|
| Number and kind of agents | One engine. In the SIM Framework it runs in three fixed roles: constructive, skeptical, arbiter | An orchestrator plus five to ten role agents | My architecture: fewer places for unattributed inference |
| Where non-determinism lives | In one place, measured by campaigns of repeated runs | In every agent and every handoff between them | My architecture |
| Attribution of a value to its evidence | Prompt version, run id, tool calls, citation state and grounding verdict on every value; every citation marked curated, retrieved or neither | Per agent; the chain across agents is reconstructed after the fact | My architecture |
| Reproducibility | Claimable: the engine is pinned, campaigns are replicated, a re-pin is recorded per claim and earlier outputs are never back-filled | Rarely claimable; agent-to-agent state drifts between runs, and an engine change is a config edit with no record of which outputs it produced | My architecture |
| Who decides | A human committee. The product emits no go or no-go and no “criterion met” | The system converges on an answer and often evaluates itself | My architecture; self-evaluation is documented as unreliable |
| Disagreement between runs | Kept and published as the spread of verdicts across repetitions | Resolved inside the loop; debate arrangements can suppress a correct minority view | My architecture |
| Silent failure | Forbidden by rule; detected and logged where it cannot be prevented | Common; one agent’s error becomes the next agent’s input | My architecture |
| Throughput per claim | Serial: one engine, one run at a time | Parallel fan-out over independent subtasks | Many-agent, on speed alone |
| Breadth of task | Narrow by design: literature review and claim inference | Broad: research, synthesis, writing and tool use in one pipeline | Many-agent, on breadth |
| Failure classes | Mechanical and testable: stalled runs, serialization, contamination on answer shape; each measured and gated | Specification ambiguity, misalignment between agents, weak verification | My architecture: my failures are visible and testable |
The test I apply, and the one I suggest you apply
For a biopharma executive evaluating an AI system for R&D, the test is the one I apply to my own work. If the output is a web page or a data pipeline, buy agents and buy speed. If the output is a scientific claim that a scientist will act on, ask four questions. Which version of which engine produced it? Was it replicated? Where did each citation come from? Who decided? A system that cannot answer those questions has produced a plausible answer, and in pre-clinical R&D a plausible wrong answer costs more than a slow right one.
The argument on this page is set out in full, with references, as a positioning paper prepared for arXiv: ↗ Attribute, Never Assert: A Single-Engine, Human-Decided Alternative to Agentic Engineering for Decision Support in Pre-clinical Drug Discovery (PDF preprint, September 23, 2026).
The verdicts in both tables are my assessment against my projects’ own standard (attribute, never assert; no silent failure; measured, not inferred), drawn from the project record and the 2026 literature. They are judgments, not measurements. Sources: ↗ MAST, “Why Do Multi-Agent LLM Systems Fail?” (arXiv 2503.13657); ↗ METR, randomized trial of AI tools for experienced developers (2025).
Engineering discipline meets AI momentum
I'm an AI Engineer with a deep-rooted foundation in systems engineering — trained to understand how complex pieces fit together, where the friction is, what the boundaries between components should be, and what it takes to make something work reliably at scale. That instinct shapes everything I build.
What excites me about this moment is the raw momentum that AI brings. The speed at which ideas can become working software has fundamentally changed. But momentum without structure produces fragile systems, hallucinated outputs, and untestable code.
AI has made Systems Engineering more critical, not less. When AI writes the code, the architect is still accountable. The value a human brings is no longer in the implementation — it is in requirements elicitation, defining module boundaries, and deciding what the system should actually do. Those are systems engineering decisions that no AI agent makes reliably without that discipline enforcing the structure.
I particularly enjoy building software appliances for R&D scientists — purpose-built tools, including project fred, that deliver autonomous, reliable research capabilities. ScienceClaw is the embodiment of this: an autonomous research platform that scientists can actually trust, built on rigorous engineering principles.
That's the thread running through all my work — from teaching scientists to vibe‑code responsibly, to building test‑first workflows that keep AI agents honest, to deploying autonomous research platforms. Two decades inside scientific R&D — understanding how experiments are designed, where data breaks down, what regulators care about, and why adoption stalls — means I build for the constraints that actually exist, not the ones that look good in a pitch deck.
Specification first, and nothing marks its own homework
I don't write the code. Claude writes all of it, and every decision about what gets built stays with me. That division only works if the process supplies the verification that confidence doesn't, so the method rests on three habits.
A specification comes before any code, and an adversarial review comes before the specification is accepted. The spec is drafted, then attacked by a separate prompt written to find fault, then amended. On one Compound Insights specification that pass found eleven defects, five of them structural — a field defined at the wrong granularity, a circular step that depended on a prompt a later step produced — all before a line of code existed. Checking while writing is not a review.
Every change runs as a script with its own guards, not as code pasted into a file. The script states what it expects to find, shows in a dry run exactly what it would change, and aborts if the file isn't what it expected. One aborted correctly on finding four matches where it expected two; the extra two were historical record and had to stay untouched.
Nothing verifies itself. A test written by the same engine it tests will confirm that engine's mistakes. Citations are re-resolved independently, a second model scores answers after being calibrated on deliberately corrupted ones, and results are compared against a stored baseline that refuses to run if the baseline itself has moved. A probe that can't go red is not a probe.
Control lives in standing instructions rather than in the conversation — personalized settings that apply to every chat, and project instructions that govern one application. Both are plain English, and neither is code. When behavior drifts, the fix goes into one of those files, not into the next message.
The whole method is written up in full, with diagrams and the presenter notes for all 23 slides: ↗ AI Coding: a practical approach for scientists — my talk at BAGIM, September 17, 2026, with Compound Insights as the worked case study.
HitchhikersAI
A non‑profit grass‑roots community accelerating the adoption of AI/ML and data in scientific R&D — starting with drug discovery & development. Members include bench scientists, data scientists, mathematicians, business owners, executives, and academics — all focused on fixing the disconnect between AI/ML/GenAI and its practical application in the lab.
AI in Drug Discovery
Regular column in Drug Target Review exploring the real‑world application of AI, ML, and generative AI in drug discovery — cutting through the hype to examine what actually works, what doesn't, and what the industry needs to do differently.
LLM in Life Sciences News Tracker
A curated tracker covering AI scientists, autonomous discovery systems, and infrastructure across pharma and biotech — from funding rounds and platform launches to partnerships and regulatory developments. Searchable and filterable by category. Updated weekly.
SLAS Discovery
Editor for the peer‑reviewed journal of the Society for Laboratory Automation and Screening, published Gold Open Access by Elsevier. Its editorial scope spans target identification and validation, assay development, biochemical and phenotypic screening, lead generation and optimization, chemical biology, and informatics — including AI and machine learning applied to drug discovery.
AI Coding: A Practical Approach for Scientists
Talk given at BAGIM on September 17, 2026: how a scientist who doesn't code can design, build, test and ship data science applications, with Compound Insights as the worked case study. The full talk is on the page — slides, diagrams and the presenter notes for all 23 slides, including the failure patterns and the checks that catch them.
I’ve spent 20 years moving between technical, commercial, and leadership roles across life sciences, semiconductors, and data infrastructure. That range matters — because the AI adoption challenge in scientific R&D isn’t purely technical. It sits at the intersection of engineering discipline, domain expertise, and the ability to navigate enterprise-scale organisations.

20/15 Visioneers
Partnered with John Conway (Founder & Chief Visioneer) to address AI adoption as the interconnected challenge it actually is — combining AI engineering, LLM agents, and in-silico software with organisational change, culture transformation, and FAIR data strategy.
incubate.bio
Founded and led a company building computational platforms for drug discovery. The core product — ALaSCA — applies Pearlian causal inference to multi-omics data. Four bioRxiv preprints: DDR resistance in cancer (2024 ↗), pathway simulation in Type 1 Diabetes (2023 ↗), causal inference in Alzheimer’s (2022 ↗), and ML target prioritisation in aging (2022 ↗).
Eagle Genomics
Led market development and product strategy across epigenetics, microbiology, multi-omics, and real-world evidence. The company’s top seller, regularly closing multi-year six-figure solution deals with blue-chip life sciences and CPG customers worldwide.
IBM Research
Led the Watson genomics programme in partnership with the New York Genome Center, reporting directly to an IBM Senior Vice President. Closed multi-million dollar agreements in healthcare & life sciences, including complex IP licensing and partnership contracts.
IBM Semiconductor Group
Program Director for Operations Research at IBM’s 300mm Fishkill fab. Led a cross-functional team across multiple IBM organisations. Developed and deployed a predictive analytics platform with IBM Research, saving $10M+. Awarded 12 patents during this period.
Top 13 Influencers in the Semiconductor Industry
Signal Integrity Effects in Custom IC and ASIC Designs
Silicon Germanium: Technology, Modeling, and Design
For the full picture — including patents, earlier publications, education, and additional roles — see my LinkedIn profile ↗